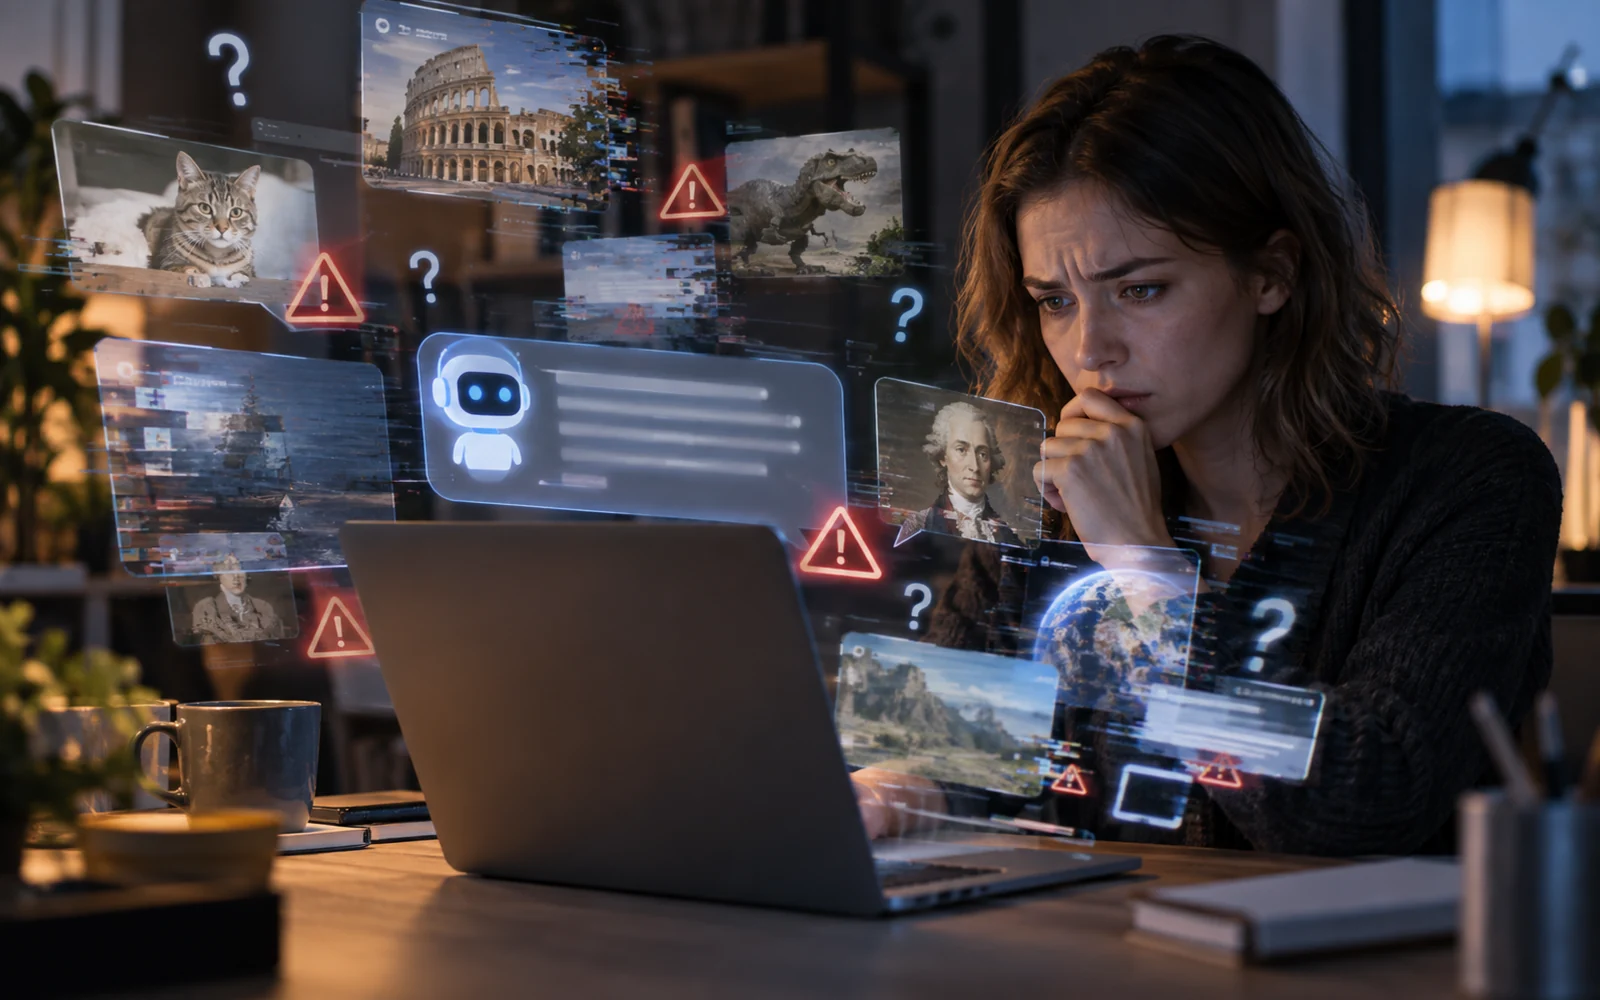
You ask a chatbot for the title of a scientific study, and without hesitation it provides the authors, year and a link. When you click it, you discover that the article does not exist. At other times, it may create a convincing biography, confuse laws or attribute a quote to a well-known person who never said it. Smooth wording is therefore weak evidence that an answer is true.
AI can make up facts because a language model generates plausible text, not an automatically verified description of reality. Such errors are called hallucinations and may include non-existent sources, incorrect dates and convincing yet false explanations. You can reduce the risk by giving specific instructions, working with real source materials and checking important claims against independent sources. Neither search nor citations are an infallible guarantee.
Does that mean AI deliberately lies?
An ordinary language model has no reason to be understood like a person with a conscious intent to deceive. When it generates incorrect information, it is more accurate to say that it has produced a false answer or a hallucination. In everyday speech, people say that it “lies,” but this term may wrongly imply intent. When assessing the output, what matters more is that the user cannot treat it as fact without verification.
Moreover, an incorrect answer does not have to be entirely fabricated. The model may merge details about two similar people, confuse the year a law was adopted with its effective date, or cite a real study in support of a claim that does not appear in it. Such combined errors are harder to detect than obvious nonsense.
How hallucinations arise
During training, language models learn patterns from vast amounts of text data. Simply put, they estimate the next parts of a text based on its context. This process allows them to produce excellent explanations, translations and working drafts, but it does not by itself create a reliable register of verified facts. Predicting a linguistically convincing answer is different from proving that the answer is correct.
OpenAI research on hallucinations also highlights a problem with evaluating models: systems may receive better scores when they guess than when they admit uncertainty. Faced with a complex question, a model may therefore fill the gap with an answer that sounds correct. If it has not learned to say “I don’t know” appropriately, the user gets a false sense of certainty.
Fabricated claims can also result from insufficient context, an ambiguous prompt or outdated information. If you ask about a recent decision by an authority without an available up-to-date source, the fluency of the answer alone cannot replace access to the exact wording. And even an available document does not guarantee that the model will interpret its exceptions or transitional provisions correctly.
The most typical errors that look trustworthy
Fictitious bibliography is a common example. A model creates a realistic study title, assigns it to a real scientist and adds a false identifier. At first glance, the result may look better than an article without sources. Verification, however, means actually opening the cited publication and checking whether it exists at all and supports the specific claim.
Another error is numbers without context. A model may claim that a product has a certain performance level, that a country adopted a rule in a precise year, or that a service costs a particular amount. If it does not have the figures from a verified, up-to-date price list or documentation, precision to two decimal places is no reason to trust the result. Generated legal citations with the wrong section also deserve attention.
Even answers in which the individual facts are correct can be misleading. The model may connect them into an incorrect conclusion, omit a material exception or mix up rules from two countries. In health, legal or financial matters, checking a single number is therefore not enough: you need to verify the logic and whether the recommendation applies to the specific case.
Does asking for sources help?
Yes, sources are useful, but only if you actually open them. Asking it to “add links” may improve transparency, but the model can also generate non-existent URLs or use a real link for an incorrect claim. A better approach is to work with specific documents, exact titles and dates that can be independently checked.
IBM describes the RAG method, in which a system first retrieves information from a selected source and then answers based on it. This kind of grounding can reduce hallucinations, but it does not eliminate them: retrieval may return the wrong document, a page may be outdated, and the model may misunderstand the text. “It has internet access” is therefore not equivalent to “it verified everything.”
For a work task, it is worth explicitly specifying which source is permitted and what should happen when information is missing. For example, the instruction “answer only using the attached price list; if anything is unclear, state that the information is not provided” is better than the general request “tell me the correct price.” Even then, responsibility for checking remains with the person who publishes the result or uses it to make a decision.
How to verify an answer in practice
First, break the answer down into specific claims. Names, dates, prices, legal obligations and statistics are easier to verify than general wording. For every important point, look for the original document: an authority’s decision, the manufacturer’s technical documentation, a scientific study or current terms and conditions. A secondary article can help you get oriented, but for a disputed detail, prefer a primary source.
Also check the timing. Information that was correct last year may not apply to today’s product or an amended law. For information from other countries, ask about the jurisdiction, and for scientific conclusions, ask whether they come from a single study or a confirmed broader body of evidence. Do not try to persuade the model that your preferred conclusion is true: it may adapt to you and produce false confirmation.
If an answer changes repeatedly after a slight adjustment to the question, that is reason for extra caution. Conversely, getting the same answer repeatedly is not proof: the model may consistently repeat the same error. What matters is independent evidence, not a confident style or the number of attempts.
When can AI be used without extensive verification?
The risk is usually lower when outlining a text, generating ideas or editing your own paragraph, provided that the model does not add new facts. The situation is different when publishing health advice, an accounting procedure or specific legal guidance. In such cases, the output should be reviewed by a person with relevant expertise and checked against sources.
A healthy habit is not to avoid AI altogether, but to distinguish between a creative aid and an authoritative source. A model can speed up preparation and draw attention to questions you might not have considered. But responsibility for the truthfulness and consequences of a publicly published claim does not rest with a well-worded sentence, but with the person who uses it.
Sources
- OpenAI – Why Language Models Hallucinate (research explanation and the problem of rewarding guessing) – https://openai.com/sk-SK/index/why-language-models-hallucinate/
- IBM – What Are AI Hallucinations? (types of errors and ways to reduce them) – https://www.ibm.com/think/topics/ai-hallucinations
- IBM – What Is RAG (Retrieval-Augmented Generation)? (working with source materials and its limitations) – https://www.ibm.com/think/topics/retrieval-augmented-generation
Gabriel Čatár
I'm interested in everyday things we encounter but don't always understand. From technology and personal finance to practical guides and fascinating facts about the world. At Offpitch, I focus on topics worth exploring in greater depth, checking the facts and explaining them in a clear, accessible way. My goal is to make sure readers take away something useful from every article.


